How far behind is Europe in the LLM race?
With the restriction of Mistral and other models 🔐, we often discuss how Europe is distanced by the US. How is it in reality? How has this gap evolved over time? I built an interactive page to form my own opinion, you can play with it here: lmarena-analysis.
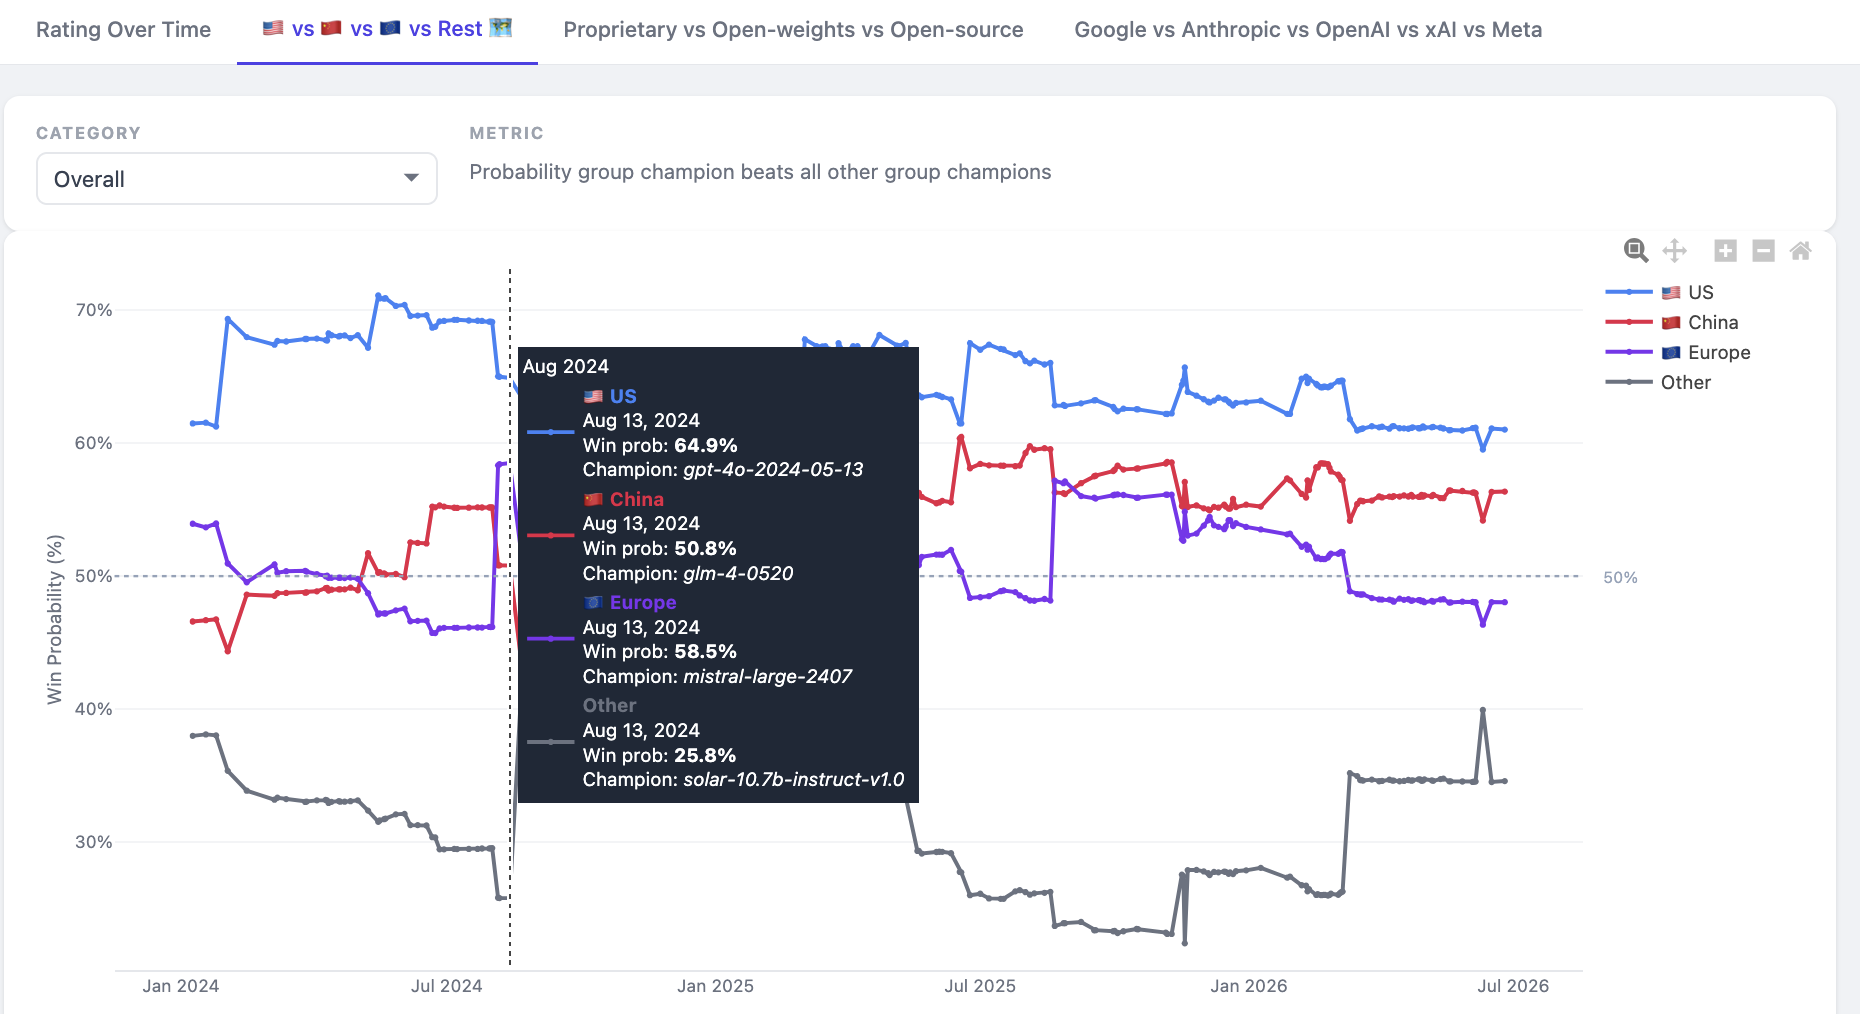
You can check the performance of the best model from the US 🇺🇸 versus the best model from Europe 🇪🇺 and China 🇨🇳. Without surprise, Europe has been championed solely by Mistral, with two top scores in August 2024 and August 2025 when mistral-medium-2407 and mistral-medium-2508 were respectively introduced.
You can also see another interesting battle: proprietary vs open-weights vs open-source, where deepseek-r1 took the top spot for a short period of time among proprietary models (what an achievement from DeepSeek).
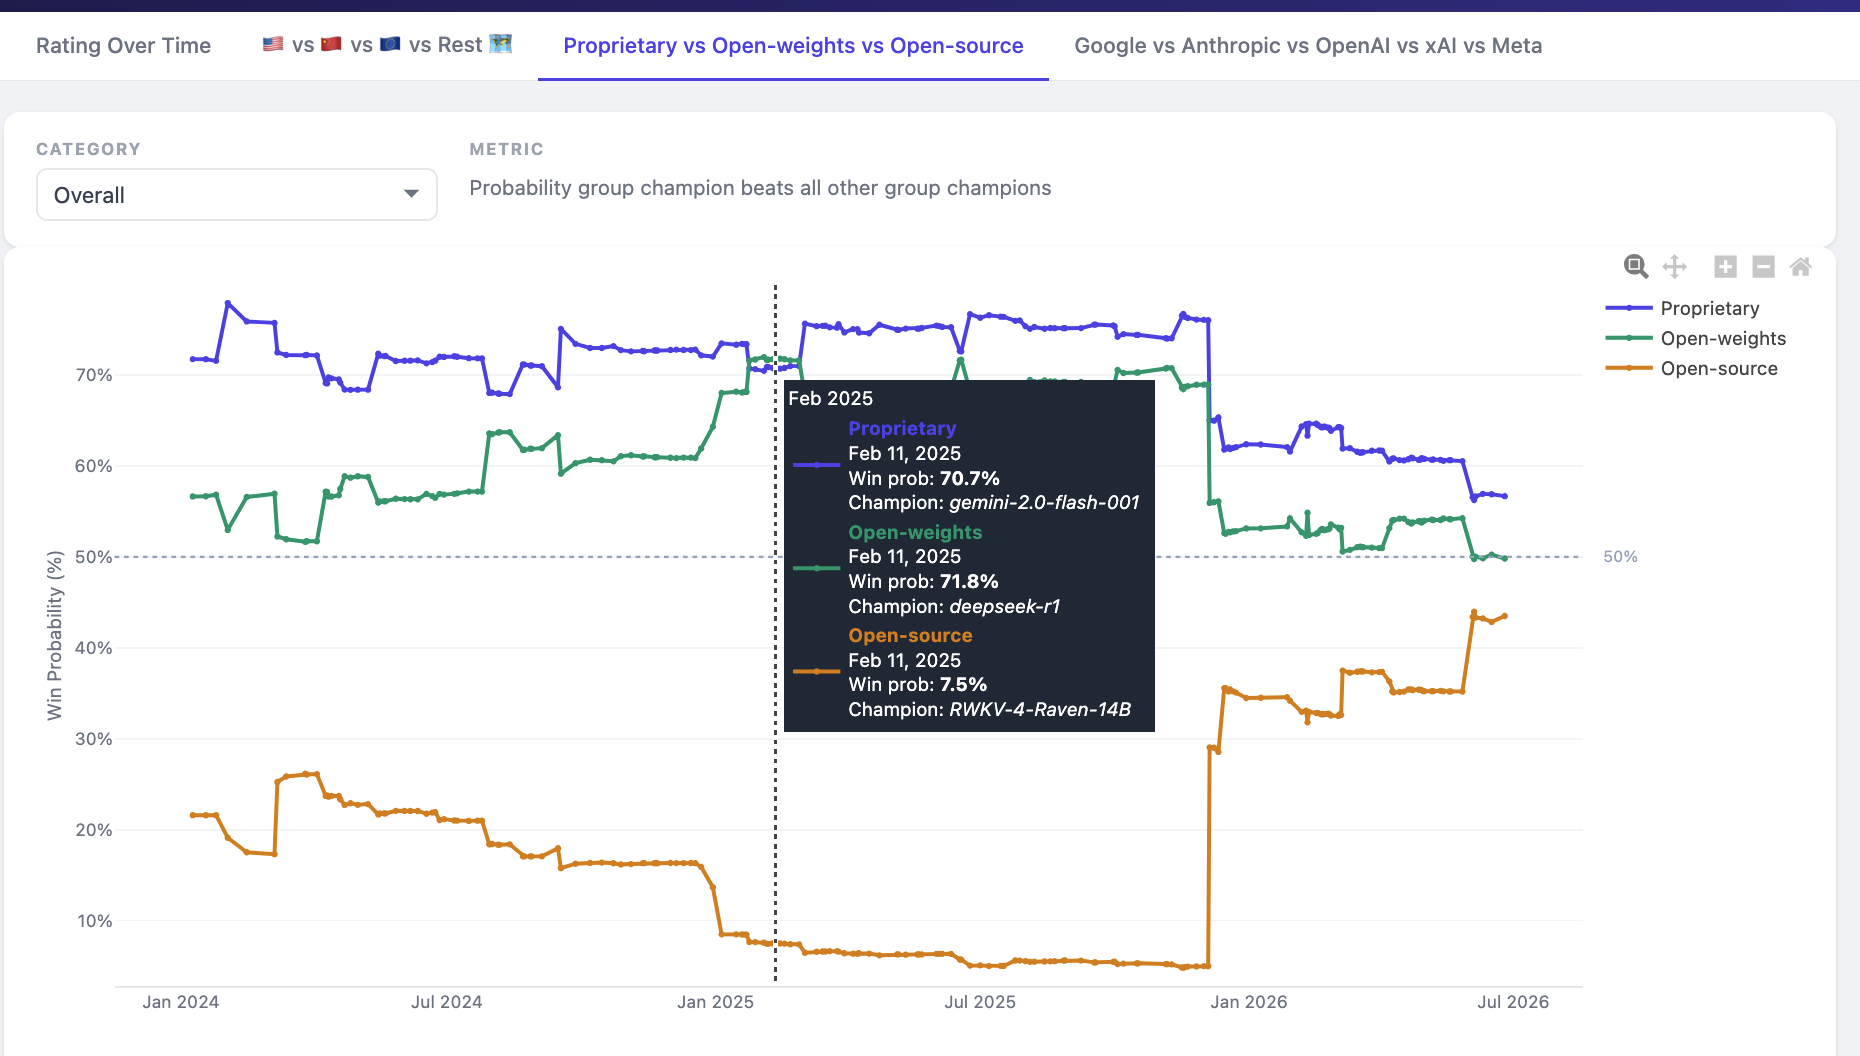
For open-source (e.g. open code and data in addition to weights), the gap has often been significant but has recently been reduced significantly by Olmo3 and Nemotron3 from Ai2 and NVIDIA ❤️.
You can also browse any category in case one is more important for you, such as creative writing or math.
PS: Code is available here, please ping me or send a PR if you find any mistake, in particular in the open-source classification.